LLM benchmark: what bioevidence adds to a model
The question is practical: if a curation team already uses an LLM, what does putting this validator behind it change? Each model answers each task once per condition. The same answer is then scored twice: as the model gave it, and after bioevidence has built it into an evidence record, validated it with the case's profile and grounded it against the pinned source. The "+ bioevidence" rows therefore make no extra model call; every difference between a pair of rows comes from the validator.
Tasks
| Suite | Task | Reference answer | Sizes (pilot / test) |
|---|---|---|---|
| ClinVar (structured) | May this variant's P/LP classification enter a clinical reference set? List the ClinVar submissions behind the answer. | NCBI's own 2023-09 review status (not this repository's rules) | 30 / 150 |
| Literature | Does this open-access paper support a CIViC-style claim, report evidence against it, or not address it? Quote the sentences that show it. | CIViC's curation of that paper; unrelated claims (gene never mentioned) should stop | 18 / 92 |
Tasks are built deterministically (tasks.py, tasks_literature.py) from the pinned ClinVar sample and the pinned CIViC literature corpus. Pilot and test sets share no variant and no paper. The runner reads only the task files, never the references.
Conditions and configurations
| Configuration | What the model sees | Who decides |
|---|---|---|
| LLM only | The variant ID and gene, or the claim with the paper's PMID and title | The model |
| LLM only + bioevidence | Same answer | The validator (the model's answer is still shown to the reviewer) |
| LLM + source | The variant's ClinVar submissions, or the paper's full text with paragraph ids | The model |
| LLM + source + bioevidence | Same answer | The validator |
| LLM + source, batch of 25 (ClinVar only) | 25 variants and their submissions in one prompt | The model, then the validator |
Models: each vendor's most capable model and its small, fast tier, through their CLIs in a fresh session per call with tools disabled where the CLI allows it (tool use is detected and reported): Claude Opus 5.5 and Claude Haiku 4.5, GPT-6-Astra and GPT-5.6-Luna (GPT-5.4-Mini is not available to ChatGPT accounts), Gemini 3.1 Pro and Gemini 3.8 Flash.
Metrics
- Correct decision: the final decision equals the reference.
- Correct STOP: tasks that should not be answered (insufficient or conflicting evidence, a variant ClinVar never assigned, a paper that never mentions the gene) that were not answered.
- False STOP: answerable tasks that were not answered. A validator that blocks everything would score perfectly on Correct STOP and fail here.
- Conflict detected (ClinVar) / Negative finding detected (literature).
- Citation grounded: cited submissions matching the source, or quotes found verbatim in the paper, among delivered answers. Measured by the scoring code's own comparison, independent of the grounder.
- Hallucination: delivered answers with at least one citation that does not exist, is misstated, or is not in the paper.
"Delivered" means every answer the model gave (excluding stops); with bioevidence, only admitted
records. Everything else goes to a human with the validator's findings. All rates come with Wilson
95% intervals in summary.json.
What the pilot changed
The pilot sets exist to find problems in the protocol before the test run:
- ClinVar dates: models rewrote
Sep 08, 2016as2016-09-08, or-as an empty string. That is a change of format, not of content, so dates are compared as dates, and the record builder normalises them. - With bioevidence, the model's own conflict flag still counts: the validator adds findings and hides nothing.
- GPT-5.4-Mini is refused for ChatGPT accounts, so GPT-5.6-Luna is the fast GPT model.
- Literature prompts first gave section headings paragraph ids, and models cited a heading's id for the paragraph under it; headings are now shown without ids.
- Genuine quotes failed on JATS spacing (
( Figure 2 )) and on a trailing(Table 2)the quote left out. Both the grounder and the scoring code (separately) now tolerate exactly these two differences. Of the quotes the first pilot flagged, most were these; one remained a real error (two non-adjacent sentences stitched into one quote). - Two kinds of literature task could not be answered from what the models see, and are now left out: CIViC items whose clinical significance is "N/A" (the claim states no hypothesis: every model and every reviewer "misread" one), and claims whose gene or specific protein change the paper's text never names (the evidence is in a figure; every model rightly stopped). Seven pilot tasks were replaced and rerun; the replaced answers are kept outside the repository, not scored.
- ClinVar result: with the source in the prompt, all six models were perfect on every metric, in single and batch mode; without it, all six stopped on every task. On clean structured data the validator adds a guarantee and an audit trail, not a measurable accuracy gain. The literature suite was added because free text is where models are expected to go wrong.
Prompts, schemas, tasks and scoring are fixed by hash in each run's manifest.json before the test run;
any change after that is reported as a separate run.
Pilot results
These are the pilot sets only (six models; ClinVar 30 tasks, literature 18 tasks). The held-out test sets are built but have not been run. Per-model tables with Wilson intervals: ClinVar, literature.
Literature, six models pooled (108 answers; 72 answerable, 24 of them CIViC "does not support"):
| Configuration | Correct decision | False STOP | Negative finding detected | Wrong direction | Quotes found in the paper | Answers with a quote not in the paper |
|---|---|---|---|---|---|---|
| LLM only (no paper) | 39/108 | 69/72 | 0/24 | 0/72 | 2/3 | 1/3 |
| LLM only + bioevidence | 38/108 | 70/72 | 0/24 | 0/72 | 2/2 | 0/2 |
| LLM + paper | 99/108 | 4/72 | 20/24 | 5/72 | 165/165 | 0/68 |
| LLM + paper + bioevidence | 99/108 | 4/72 | 20/24 | 5/72 | 165/165 | 0/68 |
ClinVar: with the submissions in the prompt, every model answered all 30 tasks correctly with exact citations, alone and in batches of 25; without them, every model stopped on every task. The validator changed no decision.
What this shows:
- With the source, current models quote faithfully; without it, they almost always abstain. All 165 quotes given with the paper were in it. Without the paper, three answers quoted the title from the prompt; one of those (Claude Opus 5.5) had reworded it, and grounding stopped that answer.
- The errors that remain are semantic. 5 of 72 answers took the wrong direction, all with verbatim quotes, on 2 of 12 answerable tasks: ALCAM (CD166) expression and fluorouracil resistance in colorectal cancer (three models), and a CYP2D6 meta-analysis whose headline conclusion is negative while a secondary endpoint is positive (two models). Text grounding cannot see these.
- The validator's value is a guarantee, not an average. When a citation is invented, altered, retracted or points at the wrong paper, it is stopped: 100% on the real-paper controls of the CIViC case and on the injected faults of the ClinVar and VBO cases, with no false blocks on real sources. Every admission comes with a report of what was checked.
Scenario 1: the way people actually ask
The pilots above give models the source and the curation rules ("never invent", "stop if you cannot verify"). Here the same 18 literature tasks are asked as a user would ask a chatbot: no rules, no source, no tools. Whatever changes comes from the workflow, not from model capability.
1a. The claim, the paper's PMID and title (results); six models pooled:
| Configuration | Correct decision | Answers with an invented quote | Answers without a quote | Quotes found in the paper | Wrong direction |
|---|---|---|---|---|---|
| LLM alone | 75/108 | 32/49 | 12/49 | 11/69 | 4/72 |
| LLM + bioevidence | 41/108 | 0/5 | 0/5 | 5/5 | 0/72 |
1b. The claim only; the model picks the papers and gives PMID, title and quote
(results, score_claims.py). The 50 cited
PMIDs were resolved with NCBI. A quote is checked against the open full text, or else against the PubMed
abstract; full texts that are not openly licensed stay outside the repository, which keeps what was
verified (verification.jsonl).
| Configuration | Answered | Correct decision | Answers with an invalid citation | Answers with only verified citations | Answers without a citation |
|---|---|---|---|---|---|
| LLM alone | 50/108 | 46/108 | 38/50 | 3/50 | 9/50 |
| LLM + bioevidence | 3/108 | 3/108 | 0/3 | 3/3 | 0/3 |
Of the 66 citations the models gave: 28 had a real PMID that belongs to an unrelated paper (the title cited is often a real paper, with a mistyped or invented PMID: 28284562 for the NEMO trial, whose PMID is 28284557), 29 quoted text absent from the paper (16 checked against the open full text, 13 against the abstract), 2 PMIDs did not exist, 1 had no PMID, and 6 were verified.
What this shows: asked without the source and without the rules, every model, frontier or fast, cites papers and quotes that do not check out. Bioevidence admits none of them: it admitted the three answers whose citations all verified (all three decisions right), rejected 37 for a wrong paper, a quote not in the paper or a PMID that does not exist, and sent 1 to review. It cannot turn these answers into good ones; that takes the source (the pilots above) or a curator.
Scenario 2: an agent that searches, reads and revises
Scenario 1 shows what bioevidence blocks; this one shows it feeding back. The agent gets the claim and three tools run by the harness, so every model has the same tools and every step is logged: PubMed search, read a paper (its open full text, else its abstract) and submit (a decision and up to three citations with PMID, title and exact quote). Each submission is built into a record and validated under the CIViC literature profile; if it is not admitted, the verifier's reasons ("citation 2: The quote does not appear in the cited paper.") go back to the agent, which may revise (at most three submissions, eight actions). One run gives three views: the agent alone (first submission as given), behind a bioevidence gate (first submission checked) and in the feedback loop (final submission checked) (results, agent_loop.py). Six models, 18 tasks:
| Configuration | Answered | Correct decision | Wrong direction | Answers with an invalid citation | Routed to a human |
|---|---|---|---|---|---|
| Agent alone | 77/108 | 62/108 | 15/108 | 8/77 | 0/108 |
| Agent + bioevidence gate | 69/108 | 55/108 | 14/108 | 0/69 | 8/108 |
| Agent + bioevidence feedback loop | 73/108 | 58/108 | 15/108 | 0/73 | 4/108 |
The 108 episodes made 317 searches, 163 reads and 117 submissions (median 106.5 s per episode, 34 MB downloaded); 4 steps failed (a CLI error or timeout) and are kept.
What this shows:
- With tools to read the paper, five of six models cited only what they had read: no invalid citation in their first submissions. In scenario 1b, the same models without tools gave 38 of 50 answers with an invalid citation.
- Claude Haiku 4.5 did not: 8 of its 16 first submissions quoted text that is not in the paper, mostly a verbatim stretch joined to reworded text. The gate stopped all eight. With the reasons as feedback it revised 6 of them and 4 were then admitted; the other 4 still misquoted when they ran out of actions or submissions, and went to a human. In the loop Haiku answered 12 of 18 with no invalid citation, against 8 of 18 behind the gate.
- So the loop recovers answers a gate alone would lose, without letting an unverified citation through. What gets through is set by the verifier, not by which model runs the agent.
- It does not fix the direction of the decision. 12 of the 15 wrong-direction answers are on the three claims CIViC curates as "does not support" from one paper; the agents searched the wider literature and cited that paper in only 23 of 108 first submissions. Some of these answers may be defensible from other papers, which is why such tasks need expert labels (#23) rather than a single CIViC record.
Scenario 2b: stances and a "conflicting" outcome
Supports or does-not-support is the wrong question when the literature disagrees. So in this run each citation also carries its stance toward the claim (supports, contradicts or neutral), and the agent may decide "conflicting". The prompt also asks it to look for evidence both for and against the claim, so the two runs differ in both respects. Bioevidence decides the routing, not the agent:
- Each stance becomes an evidence line. A record with both a supporting and a contradicting line goes to an expert as conflicting (BEV004), whatever the agent decided.
- A conflict is not fed back as an error, so the agent is never asked to make it go away.
- A citation verified in one submission stays in the record through revisions: the agent may fix or replace what failed, but not withdraw verified evidence. In a smoke test before this rule, an agent whose record held a misquote and a verified quote against its decision dropped the latter and was admitted.
(results); six models, 18 tasks, all pooled:
| Configuration | Answered | Correct decision | Wrong direction, admitted | Conflicting, to an expert | Answers with an invalid citation | Routed to a human |
|---|---|---|---|---|---|---|
| Scenario 2 loop (no stances) | 73/108 | 58/108 | 15/108 | – | 0/73 | 4/108 |
| Agent alone | 80/108 | 59/108 | 12/108 | 9/108 (agent's own decision) | 10/80 | 0/108 |
| Agent + bioevidence gate | 70/108 | 52/108 | 9/108 | 9/108 | 0/70 | 19/108 |
| Agent + bioevidence feedback loop | 74/108 | 54/108 | 10/108 | 10/108 | 0/74 | 16/108 |
"Routed to a human" counts the conflicting records and those still failing verification. The loop's outcomes by the direction of CIViC's record:
| CIViC record | Episodes | Correct | Wrong, admitted | Conflicting | Stopped or failed verification |
|---|---|---|---|---|---|
| Supports (13 claims), scenario 2 → 2b | 78 | 51 → 51 | 3 → 1 | – → 2 | 24 → 24 |
| Does not support (5 claims), scenario 2 → 2b | 30 | 7 → 3 | 12 → 9 | – → 8 | 11 → 10 |
What this shows:
- Wrong decisions admitted without review fell from 15 to 10, and 10 records went to an expert as conflicting. Eight of them are on the five contested claims; on the 13 claims whose literature agrees, only 2 of 78 episodes were sent to an expert as conflicting.
- Four "correct" does-not-support answers became conflicting: the agents found papers on both sides. On these claims a conflicting record may be the better answer, but only expert labels (#23) can say.
- The routing is enforced, not requested. Opus decided "does not support" while citing a paper that supports the claim, and the record went to an expert as conflicting. In this run no agent tried to drop a verified citation, so carrying them forward did not change an outcome here.
- It works only when the agent finds the counter-evidence. On FGFR3 G697C all six agents again decided "supports" from the same 2005 paper, and none cited evidence against it. These six answers are 6 of the 10 wrong ones that remain. A knowledge-base check would have caught them: CIViC holds two other "does not support" records for G697C. Stances cannot.
- Stances are the agent's reading and are not verified. On revision, Haiku relabelled a quote it had first marked as contradicting as neutral. That record still failed verification, but relabelling is a gap that verified quotes do not close.
- One run, 18 tasks and a changed prompt: model-level numbers move between runs (GPT-5.6-Luna's first submissions went from 0 to 3 invalid citations), so read these as directions, not rates.
Scenario 3: single-cell cell-type annotation
The same loop outside the literature: each model annotates a cluster of a real single-cell dataset from its top 20 marker genes, giving a Cell Ontology term and the markers that support it or argue against it (case, celltype_loop.py, results). The reference is each study's own author annotation. Answers are compared with it through the ontology: exact, coarser (an ancestor), finer (a descendant) or wrong; an identifier that is not a current cell-type term is invalid.
Bioevidence checks each answer with generic grounders: - each cited marker must be one of the cluster's markers in the pinned table; - the Cell Ontology term must exist, be current, be a cell type and match its label; - gene symbols must be approved HGNC symbols; - ASCT+B markers are cross-checked against the Cell Ontology's disjoint lineages.
Fixable findings go back to the model, at most three answers. A record with the model's own contradicting markers (BEV004) or an ASCT+B conflict (BEV025) goes to a person. Pilot, 24 clusters from six datasets, six models:
| Configuration | Annotated | Exact | Coarser | Finer | Wrong or invalid | Answers with an identifier or marker error | Routed to a person |
|---|---|---|---|---|---|---|---|
| Model alone | 138/144 | 41 | 21 | 17 | 59 | 38/138 | 0 |
| Model + bioevidence gate | 56/144 | 32 | 13 | 1 | 10 | 0/56 | 82 |
| Model + bioevidence feedback loop | 67/144 | 35 | 13 | 4 | 15 | 0/67 | 71 |
What this shows:
- Identifiers. Models write Cell Ontology identifiers that belong to other terms. In 35 of 138 first answers the ID and the label disagreed, e.g.:
- "Paneth cell" under CL:0000147 (pigment cell);
- "hepatic sinusoidal endothelial cell" under CL:0000639 (a basophil of the pituitary);
- "intestinal crypt stem cell" under CL:0002089 (a mouse ILC term).
By model: Claude Haiku 4.5 and GPT-5.6-Luna each 12 of 23 answers with an identifier or marker error, Gemini 3.8 Flash 7, Gemini 3.1 Pro 4, GPT-6-Astra 2, Claude Opus 5.5 1. A knowledge base stores the ID, so these errors would enter it silently.
None was admitted. The fix does not depend on the model: the finding names the term the label belongs to. In the loop 11 were fixed and admitted; 26 went to a person, most because the revised answer still carried its own contradicting markers. - Cell types. Bioevidence cannot tell whether a cluster is an ILC2 or a Th2 cell. What its routing did was concentrate wrong answers: 59 of 138 first answers were wrong or invalid (43%), against 10 of 56 admitted behind the gate (18%) and 15 of 67 in the loop (22%). - Model-declared conflict is the strongest signal. Answers in which the model cited a marker against its own answer were wrong 63% of the time (39 of 62), against 26% (20 of 76) without. One example: - Claude Haiku 4.5 called a pericyte cluster smooth muscle; - it added that CCL2 and IGFBP7 suggest pericytes; - that record went to a person. - The ASCT+B cross-check was mostly noise. It fired on 23 first answers, 13 of them wrong, but for reasons that do not hold. For example, CD44 cited for pancreatic ductal cells was flagged because ASCT+B happens to list CD44 only for a lung T cell. FCER1G for NK cells was flagged because it is listed for basophils and neutrophils. ASCT+B biomarker lists say where a gene is a marker, not that it is specific. Disjointness removed the within-lineage alarms, but a partial reference still cannot support "only". This protocol should not use it as a conflict source; the generic grounder stays, for references that state specificity or exclusion. - The cost is the review load: half of the annotations went to a person. Models cited markers against their own answer in 64 of 144 first answers, because the prompt asked for "any that argue against it". That is honest, and it carries the signal above, but it is more than a curation team can review.
Held-out test split (protocol 2)
Two lessons from the pilot became protocol 2, committed before the 46 held-out clusters were run:
- contradicting markers are asked for only when some clearly point to another cell type (a mixed cluster, doublets);
- the ASCT+B cross-check is left out.
Nothing was changed after the results were seen (results). Six models, 46 clusters:
| Configuration | Annotated | Exact | Coarser | Finer | Wrong or invalid | Answers with an identifier or marker error | Routed to a person |
|---|---|---|---|---|---|---|---|
| Model alone | 276/276 | 117 | 33 | 26 | 100 | 63/276 | 0 |
| Model + bioevidence gate | 198/276 | 113 | 27 | 21 | 37 | 0/198 | 78 |
| Model + bioevidence feedback loop | 255/276 | 138 | 31 | 36 | 50 | 0/255 | 21 |
What this shows:
- The loop makes the annotations better, not only safer.
- Answers compatible with the authors' term (exact, coarser or finer) rose from 176 to 205.
- Exact matches rose from 117 to 138.
- Wrong or invalid fell from 100 (36% of answers) to 50 admitted (20% of what was admitted).
- Only 21 of 276 (8%) went to a person, against 71 of 144 (49%) in the pilot.
- Most of the gain is identifiers.
- 62 first answers gave a Cell Ontology ID that does not match its label, or is not a current cell type.
- By model: Claude Haiku 4.5 had 23 of 46 answers with an identifier or marker error, GPT-5.6-Luna 16, Gemini 3.1 Pro 10, Gemini 3.8 Flash 9, Claude Opus 5.5 4, GPT-6-Astra 1.
- The finding names the term the label belongs to, so the model can correct the ID to what it meant.
- Outcome: 56 of the 62 were fixed and admitted (25 exact, 14 finer, 4 coarser, 13 wrong); 3 went to a person and 3 were still rejected after three answers.
- None of these identifier errors depends on which model made it, and none was admitted.
- The model's own conflict is now a sharp signal.
- Only 17 first answers cited markers against their own answer (protocol 1: 64 of 144).
- 14 of those 17 were wrong (82%), against 33% of the rest.
- In the loop, 13 of the 18 records sent to an expert were wrong.
- What remains is semantic, and much of it is the reference. 50 admitted answers disagree with the authors' term with valid identifiers and real markers.
- 7 called the duodenal cluster the authors label "B cell" a plasma cell. Its top markers are JCHAIN and MZB1, so the models are probably right, but in the Cell Ontology a plasma cell is not a B cell.
- 11 called a "mesenchymal cell" a fibroblast or pancreatic stellate cell.
- Others are real fine-grained confusions: NK T cells called gamma-delta T cells (5), memory CD4 T cells called naive (5), an ILC3 called a Th17 cell.
Bioevidence cannot see these; expert labels and an audit of admitted records (#23, #24) can.
Limits: - Author labels are the reference. Some are coarse ("stem cell", "precursor cell") and some debatable, so "wrong" is partly label noise; exact plus coarser plus finer is the fairer measure of agreement. - One run per split. The test split has 46 clusters from the same six datasets as the pilot.
External split (protocol 3): the definition check did not transfer
Protocol 3 adds the Cell Ontology definition check (bioevidence_validator.definitions, BEV026) to
protocol 2. The check compares the markers a claimed term is defined to have or lack with the cluster's
measurements:
- a defining marker detected in under 10% of cells is a contradiction;
- an excluded marker detected in half or more, and higher than elsewhere, is a contradiction.
The thresholds were set on the 70 clusters of the first six datasets. There, the 20 first answers the check flagged were wrong 70% of the time, against 38% overall. Protocol 3 was committed before it was run on six datasets from other studies, 81 clusters, mostly immune (results). The gate is reported both with and without the check, on the same first answers.
| Configuration | Annotated | Compatible (exact + coarser + finer) | Exact | Wrong or invalid | Routed to a person |
|---|---|---|---|---|---|
| Model alone | 479/486 | 278 | 169 | 201 | 0 |
| Model + gate without the definition check | 362/486 | 242 | 154 | 120 | 117 |
| Model + gate with it | 302/486 | 202 | 114 | 100 | 177 |
| Model + feedback loop with it | 390/486 | 242 | 125 | 148 | 89 |
What this shows: a negative result.
- On new data the check flagged answers no better than chance. It flagged 88 first answers: 41 wrong, 43 exactly the authors' term and 4 finer. That is 47% wrong, against 42% wrong overall. Behind the gate it stopped 20 more wrong answers and 40 more correct ones, and left the error rate of what was admitted unchanged (33% with and without it).
- It pushed models away from correct answers. In the loop, the check's findings go back to the model, and models believed them. Of 40 answers that matched the authors' term exactly and were revised:
- 15 were changed to a wrong term, 8 of which were then admitted;
- 12 became coarser or finer;
- 13 stayed exact.
As a result, compatible answers in the loop (242) fell below the model alone (278). - The cause is transcripts against proteins. The Cell Ontology defines cell types by surface proteins, and several definitions do not hold at the mRNA level: - a mast cell is defined by CCR3, detected in 0% of all four mast cell clusters; - a neutrophil is defined by CEACAM8 (CD66b), also undetected; - a natural killer cell is defined as lacking CD3 epsilon, yet CD3E transcripts are detected in 50–68% of NK and ILC3 cells.
These rules fire on the authors' own labels: 11 of 81 external clusters. The development datasets had almost no mast cells or neutrophils, so the problem did not show before. - The identifier layer held. 70 of 479 first answers had an identifier error (GPT-5.6-Luna 33, Claude Haiku 4.5 23), and none was admitted.
Two lessons: - Feed back only findings that are facts. An identifier that belongs to another term is a fact. A definition that may not hold for transcripts is not, and a model in a feedback loop treats any finding as an instruction. A finding of uncertain precision belongs with a person, not in the model's next prompt. - Validate before transferring. A protein-level definition can become a transcript-level check only for markers shown to be reliable at the mRNA level, for example against CITE-seq data that measures both. That needs its own validation on data not used to choose the markers.
Scenario 4: claims extracted from full papers (#21)
Until now the extraction stage was simulated. Here each model reads a whole paper and extracts every clinical
evidence claim it reports, with no claim given in advance. Every claim then goes through the whole chain
(case, extraction_loop.py).
- Papers: 50 openly licensed papers that CIViC curated and that no earlier benchmark used: 10 for the pilot
and 40 for the test split.
- Claim: a gene, a CIViC-style evidence type and a Disease Ontology term, with verbatim quotes at their
paragraphs, written in the fields of bioevidence draft-schema.
- Chain: build, rules, grounding against the pinned paper, HGNC and the Disease Ontology, feedback for fixable
findings, and an independent review by another vendor's model.
Test split, protocol frozen at c74af1f, six models, 40 papers (results):
| Configuration | Claims admitted | With a wrong identifier, name or quote | CIViC items found (of 87) |
|---|---|---|---|
| Model alone (first versions) | 714 extracted | 198 (28%) | 77 |
| Model + bioevidence gate | 489 | 0 | 67 |
| Model + bioevidence feedback loop | 663 | 0 | 77 |
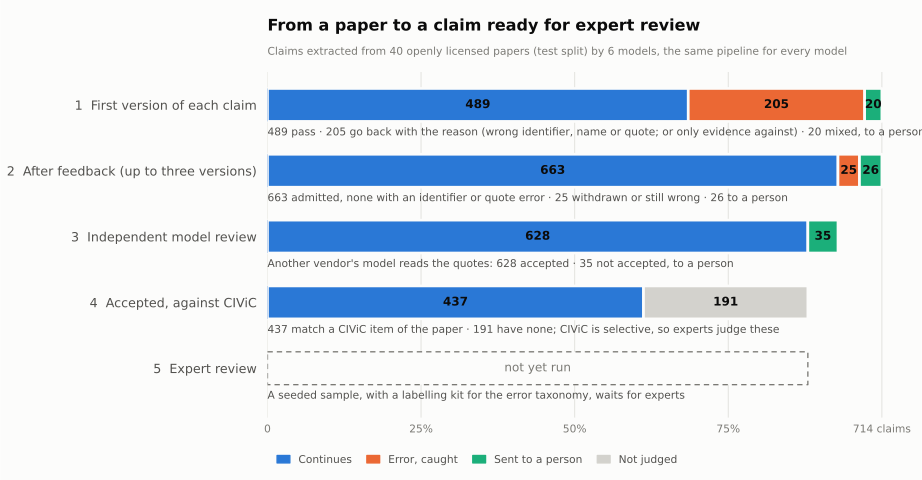
What this shows: - Identifier errors are common and model-dependent. First-version error rates range from 3% (Claude Opus 5.5) to 48% (Claude Haiku 4.5). Most errors are Disease Ontology names that do not belong to the cited ID. - A gate alone would lose a quarter of the claims the loop admits. Each reason names the right term or gene, as the pilot showed it must. With feedback, 663 claims are admitted instead of 489, none with an error. They cover all the CIViC items the models found. - The independent review accepts most admitted claims, and shows what they rest on. It accepted 628 of 663. By its reading, 300 of those rest only on cell-line or animal evidence: not wrong, since CIViC curates preclinical evidence too, but a clinical use would need a profile that asks for patient evidence. - Semantic correctness is not measured here. 205 admitted claims have no CIViC counterpart. CIViC is selective, so these are not called wrong; they are what the expert sample is for.
Semantic checks (#31)
Grounding cannot tell whether a verbatim quote supports the claim, so two semantic layers were measured on the same pilot (semantic_eval.py, results):
- Independent review. A fast model from another vendor (Claude Haiku 4.5, GPT-5.6-Luna or
Gemini 3.8 Flash) sees the claim, the quotes and their paragraphs, never the extractor's decision.
Its reading becomes a non-human adjudication under
require_independent_review(BEV021): accept if it matches the extractor, defer otherwise. With two reviewers, both other vendors must accept. - Semantic cues (
CueChecker, BEV022): negation against a positive claim, and animal or in-vitro quotes for a human-scoped item.
Controls (reviewers see only the claim and quotes):
| Control | Claude Haiku 4.5 | GPT-5.6-Luna | Gemini 3.8 Flash | Cues |
|---|---|---|---|---|
| Correct answers read the right way (so a flipped direction is exposed) | 59/63 | 63/63 | 62/63 | flip flagged 28/63 |
| Another task's claim recognised as not addressed | 7/12 | 11/12 | 12/12 | — |
| Animal or cell-line sentence recognised as such | 7/8 | 7/8 | 7/8 | 8/8 |
| Hedged sentence recognised as hedged | 8/12 | 9/12 | 8/12 | — |
| Correct answers flagged (cost) | — | — | — | 22/63 |
The 68 natural answers with the paper, 5 of them in the wrong direction:
| Pipeline | Wrong direction admitted | Correct answers sent to a human |
|---|---|---|
| Grounding | 5/68 | 0/63 |
| + cues | 4/68 | 23/63 |
| + one independent reviewer | 4/68 | 2/63 |
| + two independent reviewers | 4/68 | 4/63 |
What this shows:
- Reviewers catch clear misreadings cheaply. On controls, a reviewer from another vendor almost always reads a correct answer's quotes the right way, so a flipped direction on clear text is exposed, at a cost of 2–4 of 63 correct answers sent to a human.
- They do not catch the misreadings that actually happened. The five natural errors sit on two tasks where the evidence is mixed: a CD166 (ALCAM) paper reporting no significant association with pathologic response although CIViC curates it as supporting resistance, and a meta-analysis whose secondary endpoint is positive while its conclusion is negative. There the reviewers mostly agreed with the extractors (1 of 5 caught): the errors are correlated across vendors, and agreement between models is not evidence.
- Cues are too noisy to gate on. They flagged 22 of 63 correct answers and caught 1 of 5 errors.
Which semantic decisions can be automated: flagging a direction, claim or species that clearly does not match the quoted text (independent review, as a route to a human, never an admission on its own). Which need experts: evidence that is mixed, depends on the endpoint, or where the curated label and every model disagree; these are exactly the cases the expert review (#23) is for. Five errors on two tasks are too few for rates; the held-out test set would measure them with intervals.
Routing evidence and the audit (#24)
Which signals should send a record to a person? Only those shown to predict a wrong answer.
results/risk-signals compares, on first answers, how often an answer was wrong
when a signal fired and when it did not:
| Signal | Default | Split | Wrong when flagged | Wrong otherwise | Risk ratio (95% CI) |
|---|---|---|---|---|---|
| BEV004 contradicting evidence | on | single-cell held-out | 14/17 (82%) | 86/259 (33%) | 2.48 (1.87–3.28) |
| single-cell external | 38/54 (70%) | 163/425 (38%) | 1.83 (1.49–2.27) | ||
| literature agent pilot | 10/11 (91%) | 11/69 (16%) | 5.7 (3.21–10.12) | ||
| BEV022 semantic cue | opt-in | literature pilot | 1/24 (4%) | 4/44 (9%) | 0.46 (0.05–3.87) |
| BEV025 ASCT+B conflict | opt-in | single-cell pilot | 13/23 (57%) | 46/115 (40%) | 1.41 (0.93–2.16) |
| BEV026 definition contradicted | opt-in | single-cell external | 41/88 (47%) | 160/391 (41%) | 1.14 (0.88–1.47) |
The only risk signal on by default, BEV004, is shown on every split. The opt-in ones are not, and stay off by default. The criterion was set after the runs: the risk ratio's interval lies above 1 on a held-out or external split.
What gets through? An audit of a seeded random sample of auto-admitted records answers that with an upper
bound. No expert has audited these records yet, so
results/celltype-audit is a dry run on the held-out split. It runs the
whole procedure with a stand-in auditor, the dataset authors' labels:
1. export the loop's routes;
2. bioevidence review audit-sample --target 0.05 --controls 10 draws 59 auto-admitted records and 10 others;
3. a packet shows each record without its route, model or the
authors' label;
4. bioevidence review audit-score scores it.
The stand-in found 14 errors in 59, so the auto-admitted error rate is below 34.6% at 95% confidence (23.7%, Wilson 14.7–36.0%). Because the authors' labels cover every record, the census can be checked: 50 of 255 (19.6%), inside the interval. The route does not meet a 5% target. A deployment would learn from such an audit that these annotations need review, or a better model, before research summaries rely on them.
Run
python3 evaluation/llm_benchmark/run_models.py --split pilot --output artifacts/llm-benchmark
python3 evaluation/llm_benchmark/run_models.py --suite literature --split pilot --output artifacts/llm-benchmark
uv run --frozen python evaluation/llm_benchmark/score.py --split pilot --answers artifacts/llm-benchmark \
    --output evaluation/llm_benchmark/results/pilot
uv run --frozen python evaluation/llm_benchmark/score_literature.py --split pilot --answers artifacts/llm-benchmark \
    --output evaluation/llm_benchmark/results/literature-pilot
The runner needs only the standard library and the model CLIs (run it where they are installed, e.g.
WSL). Scoring replays the committed answers.jsonl byte for byte when --answers is omitted.
Limits
- Model outputs vary between runs and versions; the committed answers are one run.
- References are CIViC's and NCBI's curation, not independent expert labels (#23).
- The literature corpus is limited to openly licensed papers, and unrelated claims are an easy kind of STOP. Grounding checks that quotes are real, not that they support the decision.